
ABOUT REPSTANCE
Repstance is a real-time data propagation tool, which is used to keep data highly available across various databases and enable real-time data processing and analysis. Repstance is currently listed on the AWS and Azure platforms and can also be deployed outside the cloud infrastructure.
Repstance supports Oracle 10g - 19c and any version of SQL Server that permits the use of CDC (Change Data Capture) as Source Databases. Every edition targets Oracle and SQL Server; Repstance Advanced Edition also targets PostgreSQL, MySQL, Amazon Redshift, Snowflake and AWS S3 (Amazon Aurora is supported through its PostgreSQL and MySQL compatibility). See SUPPORTED DATABASE REQUIREMENTS for the full list, the versions and the two editions:
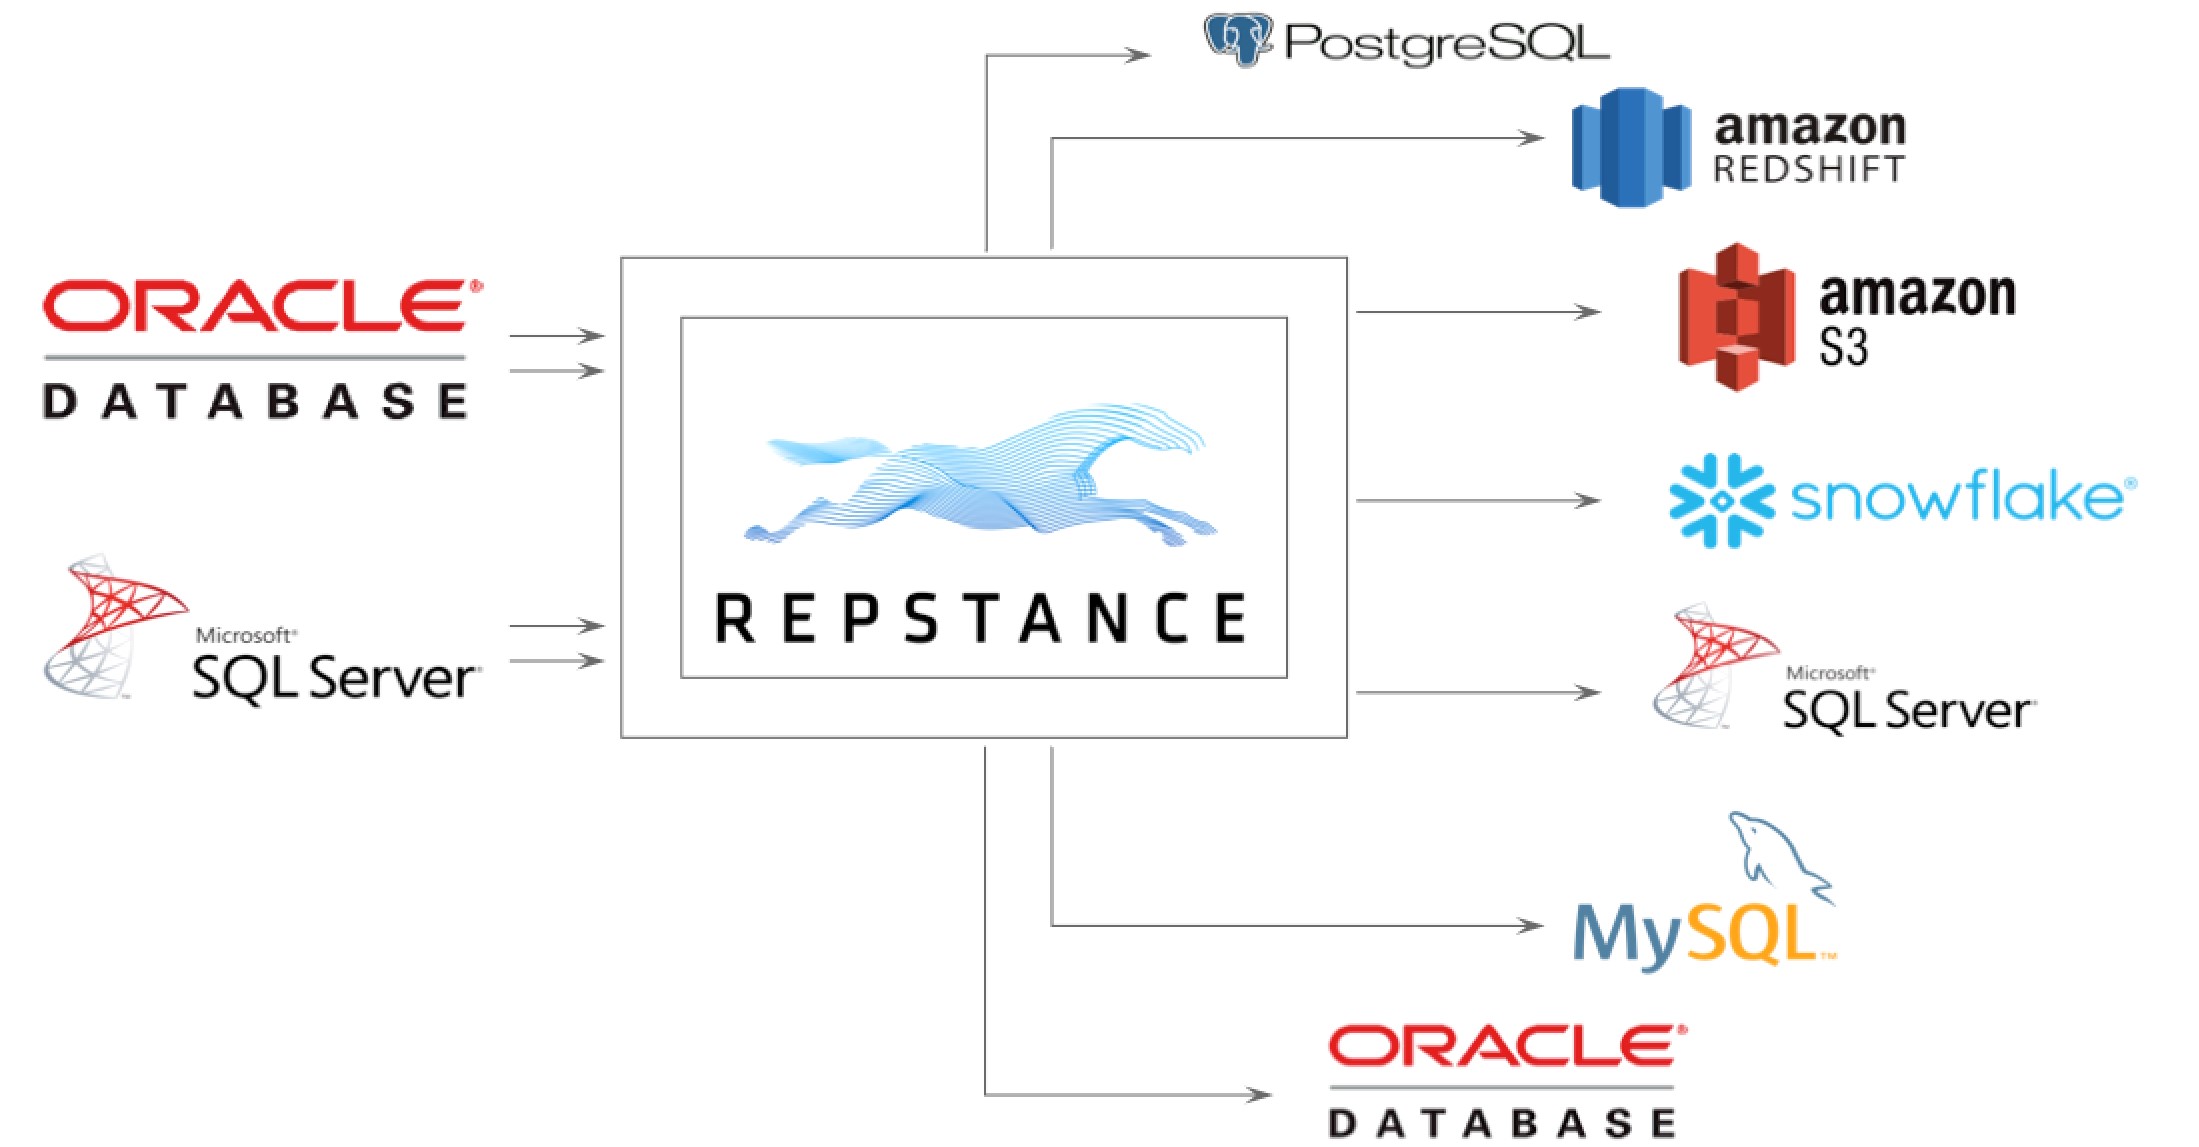
Repstance Architecture Overview
Repstance functions as Linux service. It requires access to both Source and Target Databases, in addition it needs a set of minimal Database Objects to function. To replicate data Repstance uses Capture and Apply Processes. The Capture Process extracts data from the Source Database and puts it into locally stored Trail Files in the same sequential order as the transactions occurred in the database. The Trail Files are consumed by Apply Process to insert the captured data into the Target Database. The Apply Process can also filter and modify data or/and data definition if the appropriate transformation and filtering rules are configured:
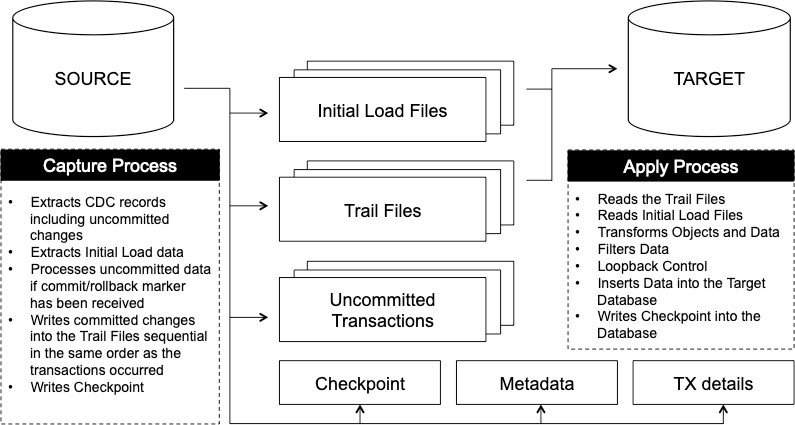
Both of the Processes, while they depend on each other to supply or insert the necessary data they, nonetheless, run as independent threads. The Capture Process does not need to have a running or configured Apply Process as it will quite simply continue extracting data using the criteria supplied, conversely the Apply Process only needs valid Trail Files from a Capture Process to consume.
See GETTING STARTED WITH REPSTANCE to deploy Repstance, INTERACTING WITH REPSTANCE SERVER for the command line, the Web UI and the REST API, and CONFIGURE REPLICATION WITH REPSTANCE for worked examples.
Prev page:
Repstance User GuideNext page:
SUPPORTED DATABASE REQUIREMENTS- Repstance User Guide
- SUPPORTED DATABASE REQUIREMENTS
- GETTING STARTED WITH REPSTANCE
- INTERACTING WITH REPSTANCE SERVER
- CONFIGURE REPLICATION WITH REPSTANCE
- DATABASE CONFIGURATION COMMANDS
- PROCESS CONFIGURATION COMMANDS
- PROCESS CONTROL COMMANDS
- DATA COMPARISON
- REPSTANCE WEB USER INTERFACE
- REPSTANCE SERVER MAINTENANCE
- MONITORING WITH AMAZON CLOUDWATCH
- MONITORING WITH AZURE MONITOR
- TROUBLESHOOTING AND FAQ
- GLOSSARY